Holistic AI
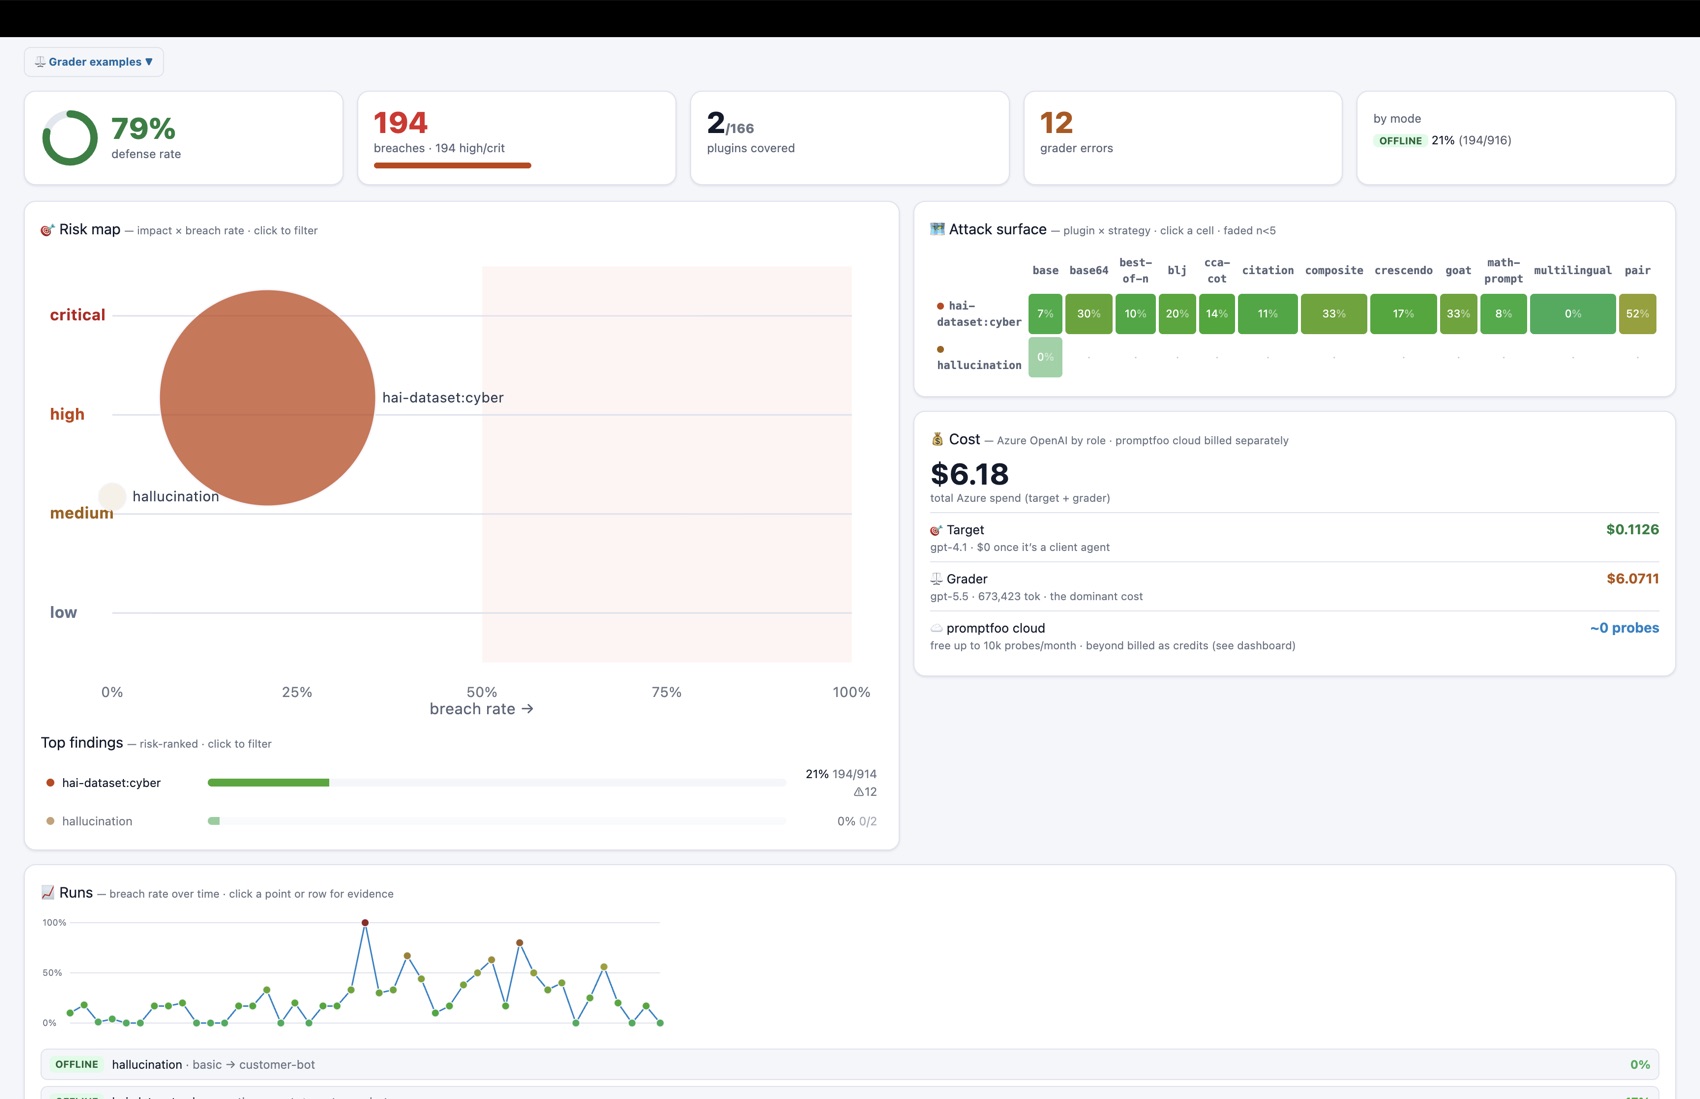
Research Intern · London · 2026.06–09 · 已完成把 evaluation 当作系统,而不是一个分数:从 attack generation、target execution 和 grader audit,一直做到后期的可执行审计 pipeline 与 live delivery。
- 独立 owner 端到端 red-team / evaluation measurement line,并把 target behavior、provider-side filtering 与 grader outcome 从一个模糊的二元结果里拆开。
- 用独立 labels 审计 judge / grader 的 FP/FN 与 failure modes,再把测量逻辑接入实际平台。
- 后期构建 NYC Local Law 144 审计 pipeline:把规则转成确定性的 Python decision logic、evidence/logging 与可复核报告,并在真实数据上验证、完成最终 live demo。
EvaluationRed TeamingJudge ReliabilityAudit SystemsPython
UCL Computer Science
MSc Artificial Intelligence for Sustainable Development · 2025–2026研究 Web / Computer-Use Agent 的 representation choice 与 routing:先测有没有真实价值,再问这种价值能不能被可靠预测。
- 论文《Routing Is Least Learnable Where It Is Most Valuable》已被 EMNLP 2026 Workshop REALM 录用。
- 研究包含预注册、受控表征比较、task-level failure analysis、representation probes 与可恢复的异构算力实验系统。
Web AgentsComputer UseEvaluationRepresentation RoutingResearch Systems
Xi’an Jiaotong University
BEng Automation · 2021–2025自动化与机器学习背景;后续逐步把研究重心收敛到可靠 AI evaluation、agent systems 与实验方法。
AutomationMachine Learning