UCL × Holistic AI Showcase · 16 Sep 2026
When Is Expensive Perception Worth Paying For?
Testing when richer web-agent representations help — and whether their value can be predicted cheaply.
Jiaming Wei · Supervisors: María Pérez-Ortiz · Zekun Wu
POSTER CASE STUDYSame task, different view
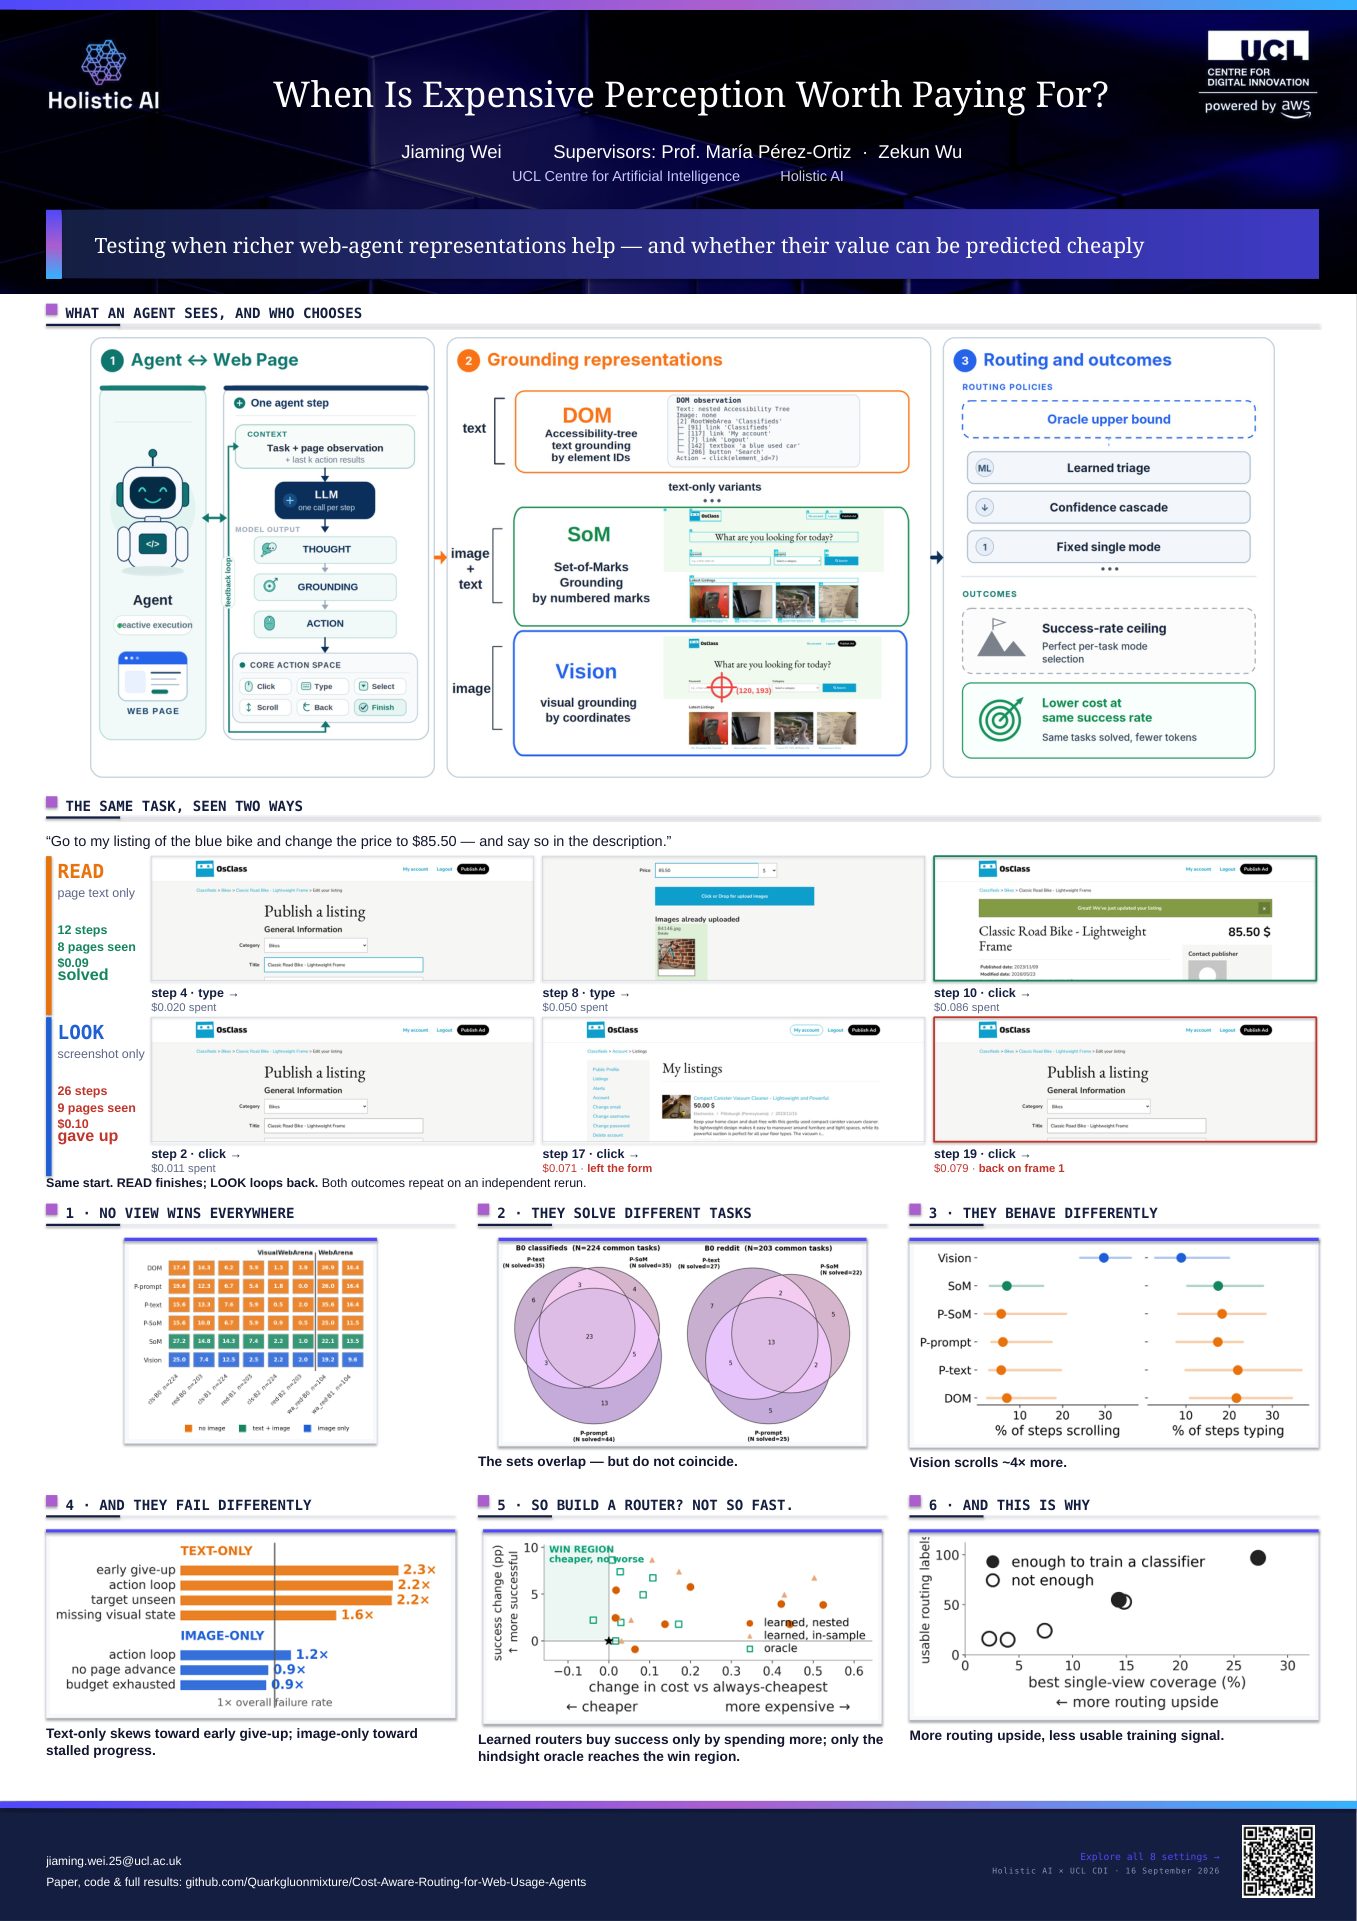
The same listing-edit task, viewed through two representations from the same start.
Both outcomes repeated on an independent rerun. This is evidence of behavioral difference, not a claim that text-only is universally stronger.
01
The six claims the showcase was built around
No view wins everywhere
DOM, SoM and vision win on different tasks; no single representation covers the full success set.
They solve different task subsets
The success sets overlap but do not coincide — the source of real routing headroom.
Their trajectories differ
Vision scrolls roughly 4× more in this analysis; representation changes the agent's action dynamics.
Their failure modes differ
Text-only skews toward early give-up; image-only toward stalled progress.
Routing value does not imply a learnable router
Learned routers tend to buy success by spending more; only the hindsight oracle reliably reaches the win region.
More upside can mean less usable supervision
The core boundary is the value–learnability gap: where adaptive choice matters most, usable labels can be sparsest and prediction hardest.
02
Research artifacts
4-PAGE RESEARCH PORTFOLIO
A fast research read before the full dissertation
The question, experimental design, negative result, mechanism diagnosis and engineering system in one visual narrative.
Open PDF ↗Make the failure trajectory part of the evidence
The public research repo keeps a demo of how the agent observes, acts, stalls and recovers instead of showing only an aggregate success rate.
Research repository ↗03
Disclosure boundary
The research conclusions shown at the final poster/showcase are public-safe; private company material, client data and internal implementation are excluded.